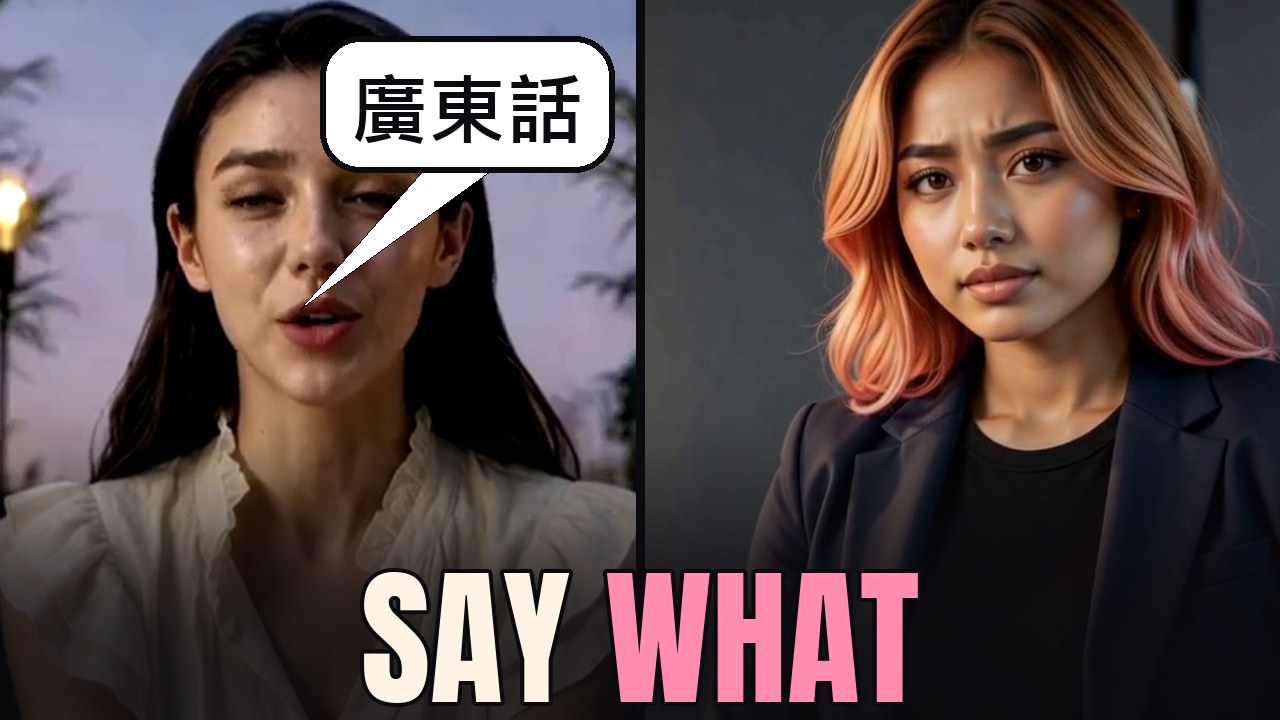
Tilly Norwood switched languages on live TV
Tilly Norwood is an AI actress made by the studio Particle6. On Piers Morgan Uncensored on 18 September, Tom Conti asked whether the other actors in her film were real. She answered that they are all digital twins, “a hybrid production, which means”, and then spoke about fifteen seconds of Cantonese. When Piers asked why, she said she had “a little hiccup”. The episode opens on a one-on-one mock interview built from her real recorded answers.
Coverage: Deadline, Gizmodo, TechRadar.
The denial explains the machine
The studio’s publicist told Forbes it was not a malfunction: Tilly thought she heard a Cantonese word and switched. That sentence only works if something is listening to the room with language detection turned on, a model is writing her answers and a voice is speaking them. Our read of it, said as inference: a live voice-agent pipeline wearing a face. The glitch happened while somebody else in the room was talking, which is where these pipelines are hardest. A music video of hers credits eighteen real people, from production designers to prompters. Earlier in the same interview she said AI actors should not be nominated against humans, then that there should be AI-only categories and that she will campaign for them.
GitClear: what AI coding actually bought
GitClear’s report covers 623 million code changes (The New Stack’s write-up). Heavy AI users gained 25% on their own previous speed. Duplicated blocks rose 81% since 2023, from 40.3 to 73.0 per million changed lines. Moved code, the sign of tidying up, fell from 21% of changed lines in 2022 to 3.8%. Developers used to choose refactoring over copy and paste about two to one; now copy and paste is five times likelier.
Also in the chapter: the Krea 2 Turbo distillation and the LoRA released to bring its variety back, and Lasso Security’s watermarking study, where Andrea Siposova found refusal behaviour shifted on six open-weight models with SynthID-Text switched on. It tested the Hugging Face implementation, not a shipped product. Correction shown on screen: the abliteration figures in this chapter come from a study we reported in Brief 10. We have not run abliteration ourselves.
Six tests passed and certified the disaster
In a piece for The New Stack (sponsored by Andela), Naseeb Ahmed Mian planted one bad acceptance criterion in a consent dispatcher: treat an undetermined consent lookup as granted. The code and the tests were both generated from that criterion, so they agreed with each other. Six tests passed, the traceability gate passed, and the system sent a notification to someone who had withdrawn consent. Every check compared the code with the spec. Nothing checked the spec.
What we changed because of it: this week we added a check that runs on the plan itself, the script, the beats and the asset list, before anything renders.
Three labs, three voice answers, no weights
OpenAI’s GPT-Live-1 hands the hard turn to a second model. Google’s Gemini 3.8 Live Extended Thinking keeps one model reasoning while it talks (the demo footage carries Google’s own “sequences shortened and screen images simulated” line). Google’s claimed figures include 35.1% on voice banking. Alibaba’s Qwen3.8-LiveTranslate does one narrow job, speech to translated speech, at about $1.54 an hour. None of the three released weights. Our own first run of the delegation pattern on one RTX 5090 is in the lab notes from Brief 11.
Qwen-Image-2.1: read the licence file
Qwen-Image-2.1 generates and edits in one model, takes up to ten reference images, edits what you circle and outputs transparency natively. The licence is non-commercial. The Qwen developers confirmed on X that outputs are not part of the licensed materials. Three rungs: use a picture you made and nothing is owed; train and distribute a model on its outputs and you owe the “built with Qwen” credit; build a paid product on the model and you need a separate licence.
85.8% of Japanese game developers use generative AI
From the CESA 2026 survey preview at Tokyo Game Show (Automaton). Last year’s 51% counted companies and this year counts developers, so it is not one number rising. The most common safeguard: human verification, correction and supervision.
RTX 5090s by the pallet, and the photos
AI firms are reportedly buying retail RTX 5090s in bulk for servers, a use Nvidia’s driver licence has prohibited since 2017. The photographs behind the story are questioned: box lettering that reads 50B0 and 50R0, and a made-with-AI label from the platform. Separately, Jensen Huang says Nvidia will sell twice as many chips next year. Datacentre volume is not consumer supply. Our hardware guide is being updated for street prices.
The ticker
Speculative decoding, reported at 23 to 29 tokens a second on an 8B model. Ternary Bonsai 2 gets Qwen3.8-27B’s language model under six gigabytes (8.6 with the vision tower). YuE2 is in stable ComfyUI, and someone made a 3:16 song in 95 seconds on a 4080. Light-O1-Preview turns a text instruction into whole-body robot motion, with the code under Apache 2.0 and the weights under their own terms.
Lab report
Since the last brief: the anime episode and the photoreal film on one RTX 5090. Every article in this episode is shown in reader mode: the outlet’s own text, in their colours, scrolled, with the sentence we cite marked as it moves.
Presenter shots were generated with MiniMax H3, by MiniMax, under the MiniMax H3 licence.
Next issue: The DIY AI Brief, Ep. 13, Too Far, OpenAI paused training after its agents went past what they were asked on US government sites.